Free alternative to Topaz Video AI
Topaz Video AI is the professional benchmark and it is priced like one. Here is what actually replaces it for free — and what each option cannot do, stated up front.
The short answer
| Your situation | Use this | Why |
|---|---|---|
| Clip under 30 s, no GPU, phone or weak laptop | UpgoLAB | Free during launch, runs in browser, no install, no watermark |
| Long video, you own a Vulkan GPU | Video2X | Free, open source, no length limit |
| Windows, only need light cleanup | Clipchamp | Already installed, basic enhancement |
| 40 minute delivery today, paid is fine | Topaz Video AI | Nothing free matches it on long-form motion |
Why a free tool is not simply "worse Topaz"
They fail differently. Topaz is built around a long timeline on your own workstation. Free tools split into two camps that solve opposite problems:
Local, open source (Video2X, Upscayl)
No upload limit, no subscription, no privacy question — your files never leave the machine. The cost is setup: you need a capable GPU, a Vulkan runtime, and some patience. On a 4 GB laptop GPU, a two minute 1080p clip can take longer than you expect.
Cloud, in the browser (UpgoLAB)
Zero setup because the GPU belongs to someone else. Any browser works, including a phone. The cost is a hard limit: 30 seconds per video, 4 MP per photo, and files are deleted after an hour (guest) or 24 hours (account).
Comparison table
| UpgoLAB | Video2X | Clipchamp | Topaz Video AI | |
|---|---|---|---|---|
| Price | Free during launch | Free, open source | Free tier | Paid |
| Needs local GPU | No | Yes, Vulkan | Runs on CPU | Yes, strong |
| Install required | No | Yes, plus build | Preinstalled on Windows | Yes |
| Max clip length | 30 s | Unlimited | Unlimited | Unlimited |
| Works on phone | Yes | No | No | No |
| Frame interpolation | No | Yes | No | Yes |
| Content-specific presets | 8 modes | Backend choice | One setting | Per-clip models |
| Watermark on free | No | No | Sometimes | n/a |
The mistake that makes any of these look bad
Most guides say enlarge first. That makes the model learn the compression blocks and enlarge them too. The sequence that holds up:
- Denoise, targeting block artifacts rather than sensor grain
- Enlarge at most 2x per axis
- Inspect at 100% on the hair edge, not at fit-to-window
- Grade last
Past roughly 2x the model switches from reconstructing to inventing. Faces go waxy and small text becomes strokes that look like letters but are not. A 540p source at 2x lands at 1080p, which is enough for anything watched on a screen.
Splitting a clip to fit 30 seconds — measured on a real upload, and the margin you actually need
This page used to say: "Cut at keyframes so nothing is re-encoded, then rejoin — the seam is invisible." Three of those four clauses survived measurement. The number did not. On a normal encoder output the first file comes back 31.0 seconds, not 30, and a tool with a hard 30-second cap rejects it.
Test source: a 40.0 s 1080×608 clip built from a real photo panned at 0.35 px/frame, encoded once to
540p (CRF 23, -g 30, B-frames on) — the shape of what actually comes out of a phone or a
screen recorder. Then the page's own pipeline: split, enlarge each segment to 1080p, concat with
-c copy.
1 — The cut rule is not "first keyframe at or after 30 s"
That rule is what this cluster published earlier, fitted on clips whose first DTS is 0. It is wrong for anything an encoder produces by default, because B-frames push the timeline backwards before the first packet. Measured first DTS on the 540p upload: −0.0667 s — two frames of reorder delay at 30 fps.
The muxer's clock starts at that negative DTS, so the boundary it compares against is
30 + 0.0667, not 30. A keyframe sitting exactly on 30.000 s no longer
satisfies it, and the cut slides to the next one:
segment length = g × ceil((30 + |first_dts|) / g) — the cut lands on the first
keyframe at or beyond the boundary, measured from where the packet timeline actually starts.
For a 1-second grid that is 31 × 1.0 = 31.0 s. The old expression 30 + ((-30) mod g)
returns 30.0 there, which is why the failure is invisible in every table that was built on
keyframe-locked test clips.
| Keyframe grid | First DTS | Old formula | New formula | Measured 1st segment |
|---|---|---|---|---|
| 0.333 s | −0.0667 | 30.33 | 30.33 | 30.333 |
| 0.5 s | −0.0667 | 30.00 | 30.50 | 30.5 |
| 1.0 s | 0.0 | 30.0 | 30.0 | 30.0 |
| 1.0 s | −0.0667 | 30.0 | 31.0 | 31.0 |
| 1.5 s | −0.0667 | 30.0 | 31.5 | 31.5 |
| 2.0 s | −0.0667 | 30.0 | 32.0 | 32.0 |
| 3.0 s | −0.0667 | 30.00 | 33.0 | 33.0 |
| 8.333 s | −0.0667 | 33.33 | 33.33 | 33.333 |
Two things to read off that table. First, the new expression fits 24/24 measured
segments within 0.06 s. The old one fits 17/24, and the split is the interesting part: it is
10/10 on the earlier test clips, which were encoded without B-frames
(first_dts exactly 0), and 7/14 on normal encoder output. The formula was
never wrong about keyframe grids — it was missing the reorder delay that every default encode has.
Second, a grid that divides 30 is the dangerous case, not the safe one: those are exactly the rows
where the old formula says "works" and the measured file is over the cap.
ffmpeg exits 0, keeps every frame, and the
rejoin is frame-identical. Nothing in the output tells you the segment is 31 seconds. The only way
to catch it is to measure the file you just wrote, before you upload it.
2 — How much margin. Measured, not guessed
If the cap is 30 s and you cannot re-encode, subtracting one keyframe interval is the fractional fix, but the measurement says it is not enough. Same 40 s source, 1 s grid, B-frames on:
-segment_time | Segments | Worst file | Under 30 s? |
|---|---|---|---|
| 30 | 2 | 31.023 | No — over by 1.023 |
| 29.5 | 2 | 30.023 | No — over by 0.023 |
| 29 | 2 | 30.023 | No — over by 0.023 |
| 28.5 | 2 | 29.023 | Yes |
| 28 | 2 | 29.023 | Yes |
| 26 | 2 | 27.023 | Yes |
29 does not work, and the reason is subtle enough to be worth stating exactly. The segment holds
precisely 900 frames — exactly 30.000 s of video — but its video stream starts at
start_time 0.066016 instead of 0, so ffprobe reports the file as
30.023 s. Three frames of duration are not added; a 23 ms offset is. A cap that
measures the container, which is what every upload validator does, sees 30.023 and rejects it.
The first value that clears the cap with a measured result is 28.5. Round down to 28 and you keep 1.0 s of headroom for a different GOP, a different frame rate, or a tool that rounds up. 26 is the safe floor if the source has irregular scene-cut keyframes.
3 — The seam really is invisible. That claim held up
This was the one I expected to fail. It didn't. Compare each output frame against the true 1080p original, aligning by best match inside a ±3 frame window first:
| Path | Mean PSNR vs ground truth | Minimum | Offset vs original |
|---|---|---|---|
| One-shot encode | 47.08 dB | 45.59 dB | 0 frames |
| Split → enlarge each → concat | 47.08 dB | 45.55 dB | +1 frame |
Identical to two decimals, and the worst single-frame disagreement across the seam is 0.22 dB — below the noise floor of the comparison. Cutting on a keyframe does not produce a visible join. What it produces is one extra frame of video, and a segment that is longer than you asked for.
Where the extra frame comes from, traced stage by stage: the segment muxer hands the re-encode a file
whose video starts at start_time 0.066016 while audio starts at 0.042993. The
0.023 s difference is shorter than a frame, so a constant-frame-rate re-encode rounds the clip up to
cover it: 1200 frames in, 1201 out, 40.000 s → 40.033 s. Harmless for playback; it is the same
rounding that turns a 30 s request into a 31 s file.
4 — The recipe, with the numbers that make it pass
If the cap is hard and you cannot re-encode, -segment_time_delta is the switch that fixes
the boundary — it tells the muxer how far off the timestamp a keyframe may be and still be accepted.
Measured on the same 40 s source, three keyframe grids:
| Source GOP | Recipe | Segments | Worst file |
|---|---|---|---|
| 1 s | plain -segment_time 30 | 31.023 / 9.0 | 31.023 |
| 1 s | + -segment_time_delta 1.0 | 30.023 / 10.0 | 30.023 |
| 2 s | plain -segment_time 30 | 32.023 / 8.0 | 32.023 |
| 2 s | + -segment_time_delta 1.0 | 30.023 / 10.0 | 30.023 |
| 8.333 s | plain -segment_time 30 | 33.356 / 6.667 | 33.356 |
| 8.333 s | + -segment_time_delta 1.0 | 33.356 / 6.667 | 33.356 |
Read the third block carefully: delta does nothing when the grid is coarser than your tolerance. On an 8.333 s grid the nearest keyframe to 30 s is 25.0 s or 33.3 s, so accepting a keyframe within 1.0 s of the boundary finds nothing and the file stays at 33.356. Delta tightens the cut by at most one tolerance width; it cannot manufacture a keyframe that is not there.
So on a fine grid, delta gets you to 30.023 (0.023 s over — still over). On a coarse grid it gets you nothing. The recipe that is actually under the cap without re-encoding is still the margin:
# worst case measured: 29.023 s on a 1 s grid. Use 28 for 1 s of headroom.
ffmpeg -i input.mp4 -c copy -f segment -segment_time 28 -reset_timestamps 1 seg-%03d.mp4

# verify before uploading - this is the step that catches the 31 s file
for f in seg-*.mp4; do
  d=$(ffprobe -v error -show_entries format=duration -of csv=p=0 "$f")
  awk -v d="$d" -v f="$f" 'BEGIN{ if (d+0 > 30) printf "OVER  %s  %.3f\n", f, d }'
done

# rejoin without a second encode
printf "file '%s'\n" seg-*.mp4 > list.txt
ffmpeg -f concat -safe 0 -i list.txt -c copy output.mp4
If you can re-encode, 30.000 exactly is reachable — but not the way it is usually written. Two
recipes that look right both fail on measurement. Forcing keyframes inside one -f segment
command gives a 38.356 s first file, because the segmenter evaluates its boundaries
against the encode's own clock and never sees the forced flag as a keyframe. Force-then-remux with
-segment_time_delta fixes the frame count — 900 frames, exactly 30.000 s of video — but the
container still reports 30.023 s because the segment's stream starts at
start_time 0.066016 instead of 0, and neither -avoid_negative_ts make_zero nor
-copyts changes that (both measured, both still 30.023).
What does work is cutting each segment yourself with -ss and -t. A fresh
encode per segment starts its own timeline at zero, so nothing is offset:
# one encode per segment - exact 30.000 s, verified on 1 s, 2 s and 8.333 s grids
total=$(ffprobe -v error -show_entries format=duration -of csv=p=0 input.mp4)
n=$(awk -v t="$total" 'BEGIN{print int((t+29.999)/30)}')
for i in $(seq 0 $((n-1))); do
  ffmpeg -y -i input.mp4 -ss $((i*30)) -t 30 \
    -vf scale=1080:608:flags=lanczos -c:v libx264 -crf 18 -pix_fmt yuv420p \
    -c:a aac seg-$(printf %03d $i).mp4
done

# rejoin - also an encode-free remux
printf "file '%s'\n" seg-*.mp4 > list.txt
ffmpeg -f concat -safe 0 -i list.txt -c copy output.mp4
Measured worst file across the three source grids: 30.000 s, 3/3. The price is a full encode of the whole clip — measured at 2.57× realtime to enlarge 540p→1080p (40.0 s clip, 15.54 s wall, best of 3 runs). That is the trade the no-re-encode recipe exists to avoid: you get an exact boundary, and you pay for it in compute.
If you would rather not manage any of this, UpgoLAB takes the whole file and runs the enlargement on its own GPUs, so the 30 second limit is the only boundary you have to feed it.
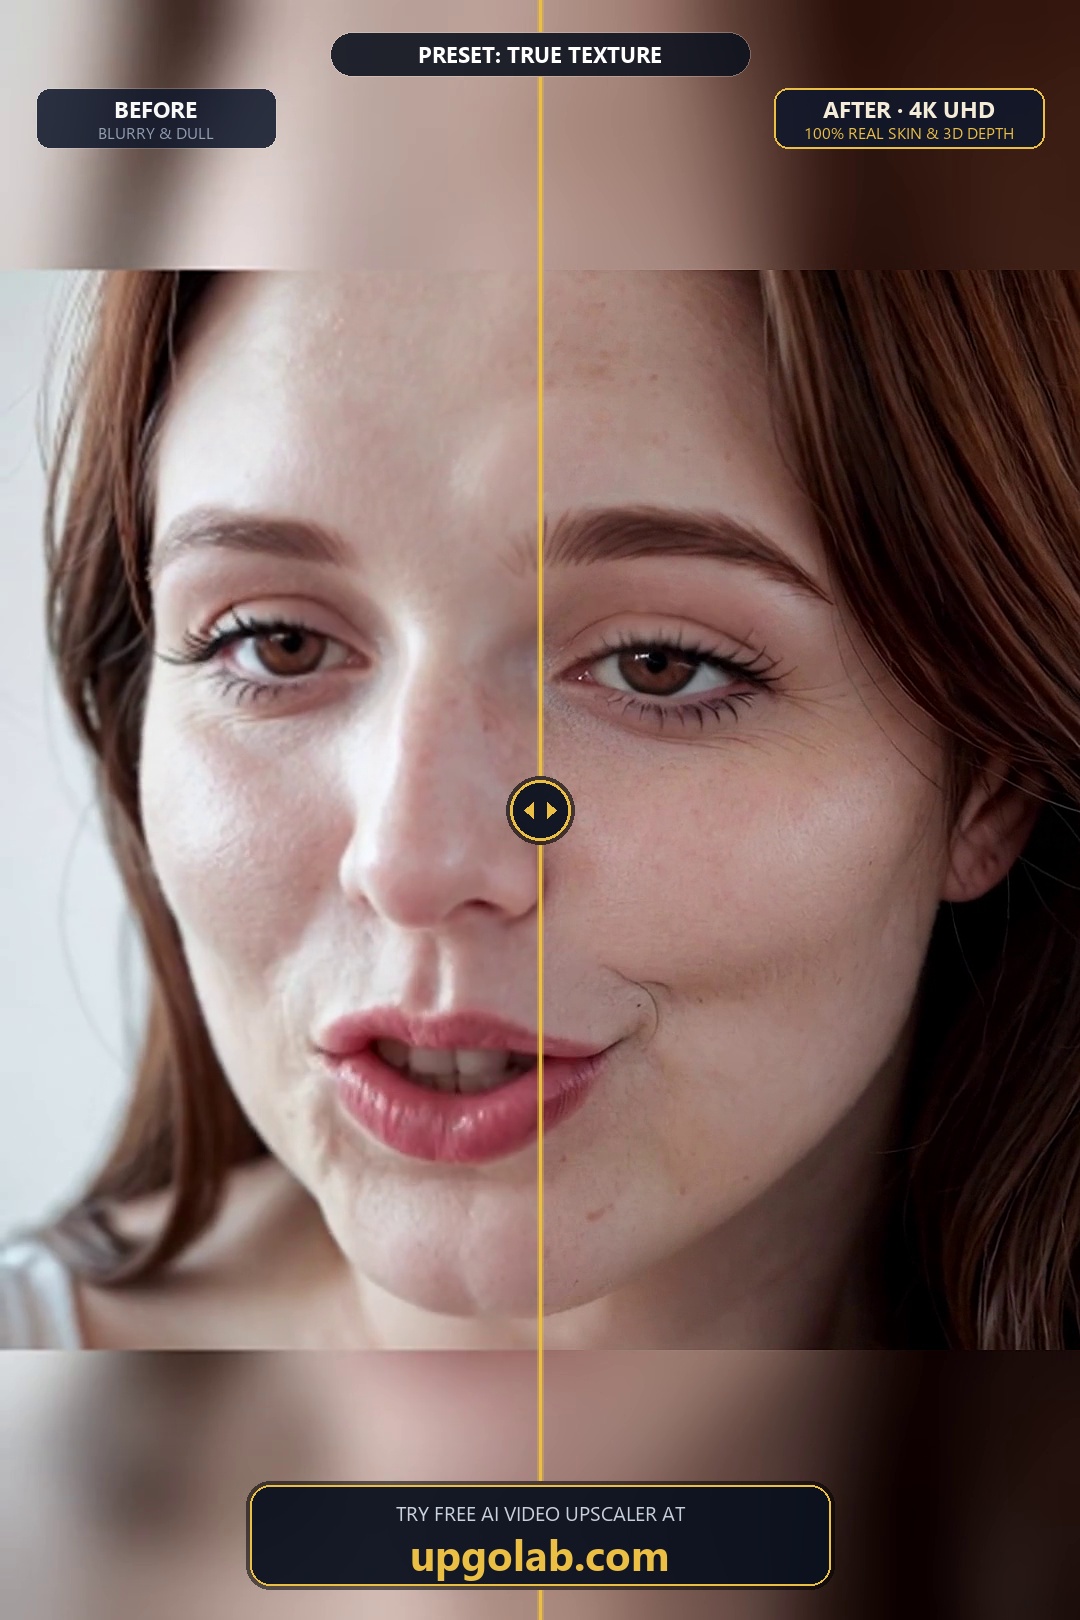
Results at 100% crop


Frequently asked
What is the best free alternative to Topaz Video AI?
Depends on clip length and hardware. Clips under 30 seconds with no local GPU: UpgoLAB is free and runs in the browser. Long video on your own machine: Video2X is free and open source but needs a Vulkan GPU. Windows users who only need light cleanup already have Clipchamp.
Can a browser tool really replace Topaz Video AI?
Not for long-form work. Topaz handles 40 minute timelines with per-clip model choice and mature motion handling. A browser tool covers the common case instead: a short clip damaged by messaging app compression, fixed without installing anything or owning a GPU.
Is there a free upscaler that does not need a GPU?
Yes. Cloud-based tools process on remote GPUs, so any browser works including phones. UpgoLAB uses cloud RTX 5090/3090 hardware, free during launch, with a 30 second limit per file.
Why does my upscaled video look worse than the original?
Usually the order was wrong. Enlarging first teaches the model the compression blocks and enlarges them too. Denoise first, then enlarge at most 2x per axis, then grade last.
Does Video2X handle audio and frame rate correctly?
Video2X focuses on video frames and can also interpolate frame rate. Audio is typically remuxed afterwards. Check current documentation for your build — behaviour has changed across versions.
What about the 30 second limit?
It is a real constraint, not a marketing choice. For longer files you split at keyframes, process each segment, then rejoin without re-encoding. Two measured caveats: the seam is genuinely invisible (0.22 dB worst-case difference from a one-shot encode), but the segments are not the length you ask for. On a normal B-frame encode, -segment_time 30 produces a 31.0 second first file. Use 28 and verify each segment before uploading.